LEO INFERENCE CARD / PCIe + CXL
LeoInfraCard
One card, two roles. Inference hardware when you need compute; CXL memory when you need memory.
01 / TWO ROLES
An inference engine or a memory expander,
switched as you need.
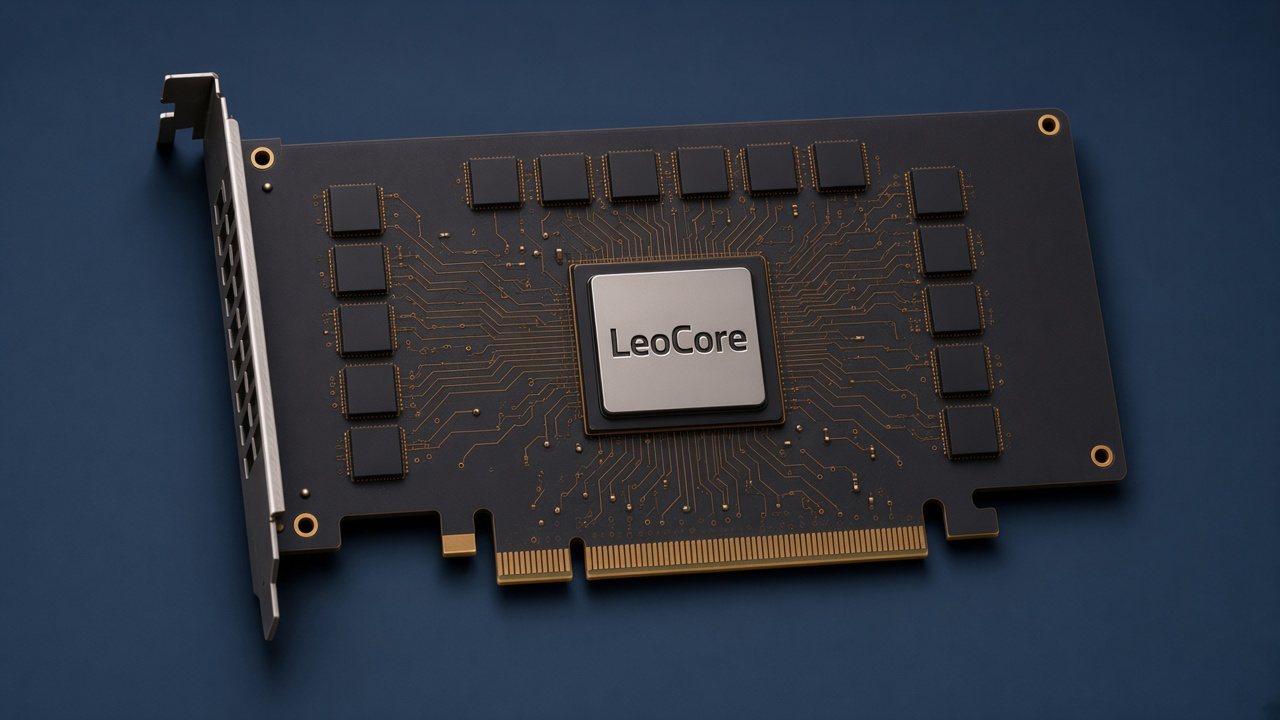
Most cards do one job. LeoInfraCard does two. Point it at a model and it is an inference engine with the model held in its own memory. Point the system at its memory and it is a CXL memory device, mapped into the host and shared with the network. One design, two targets.
Inference near memory
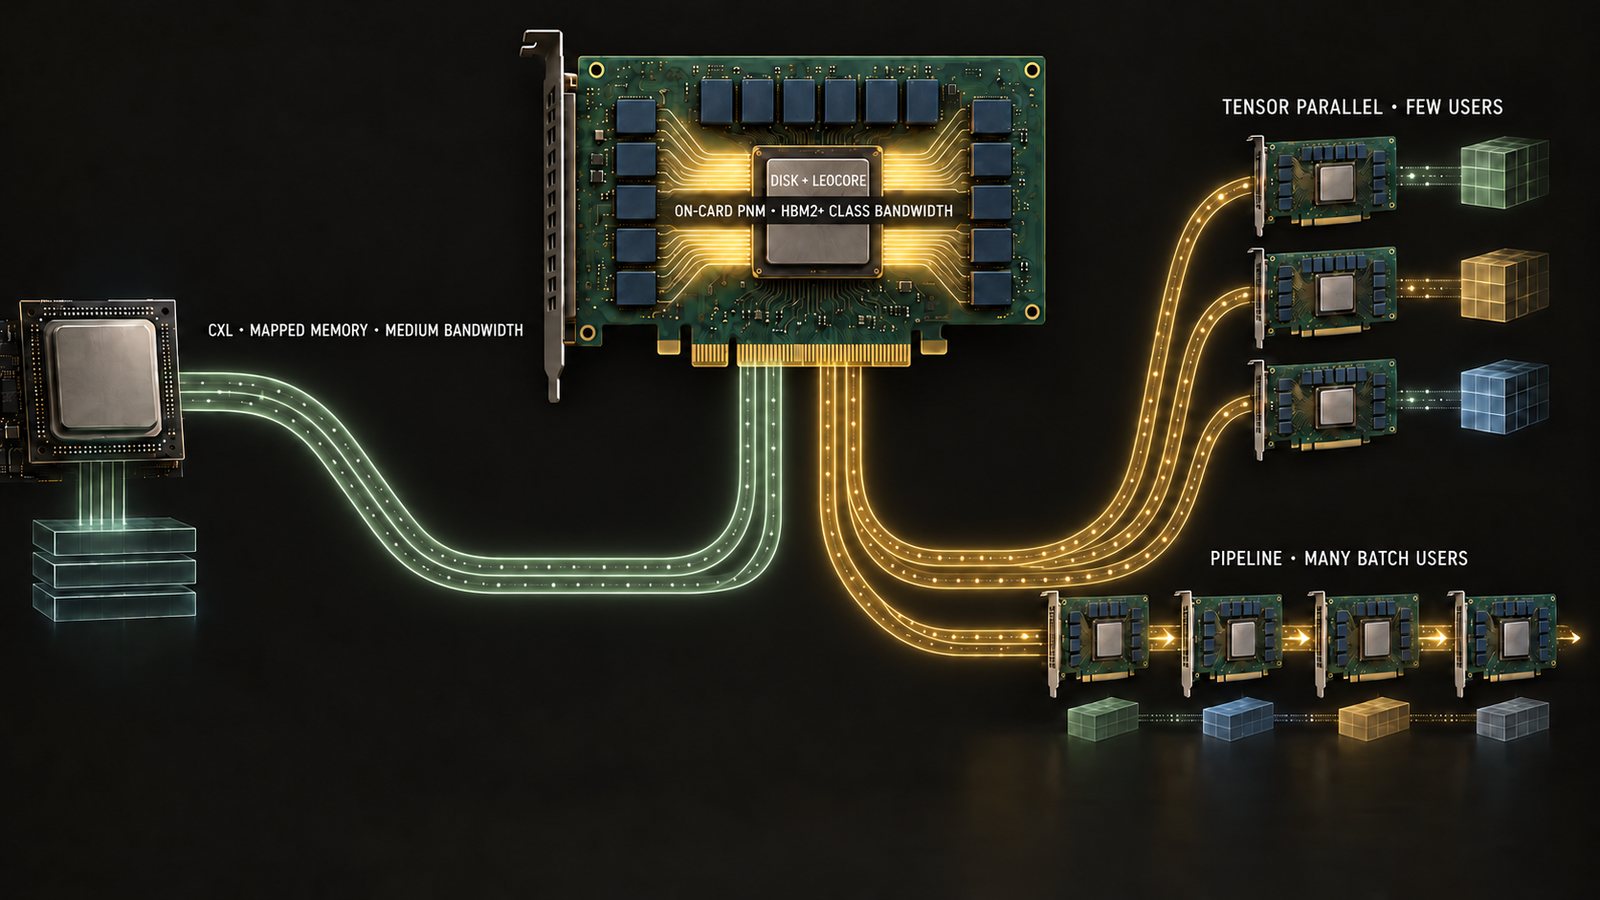
The model sits in the card’s own memory and LeoCore computes right beside it, so weights never cross the host link. Designed for 5–10× the inference speed of a GPU.
Memory for the network
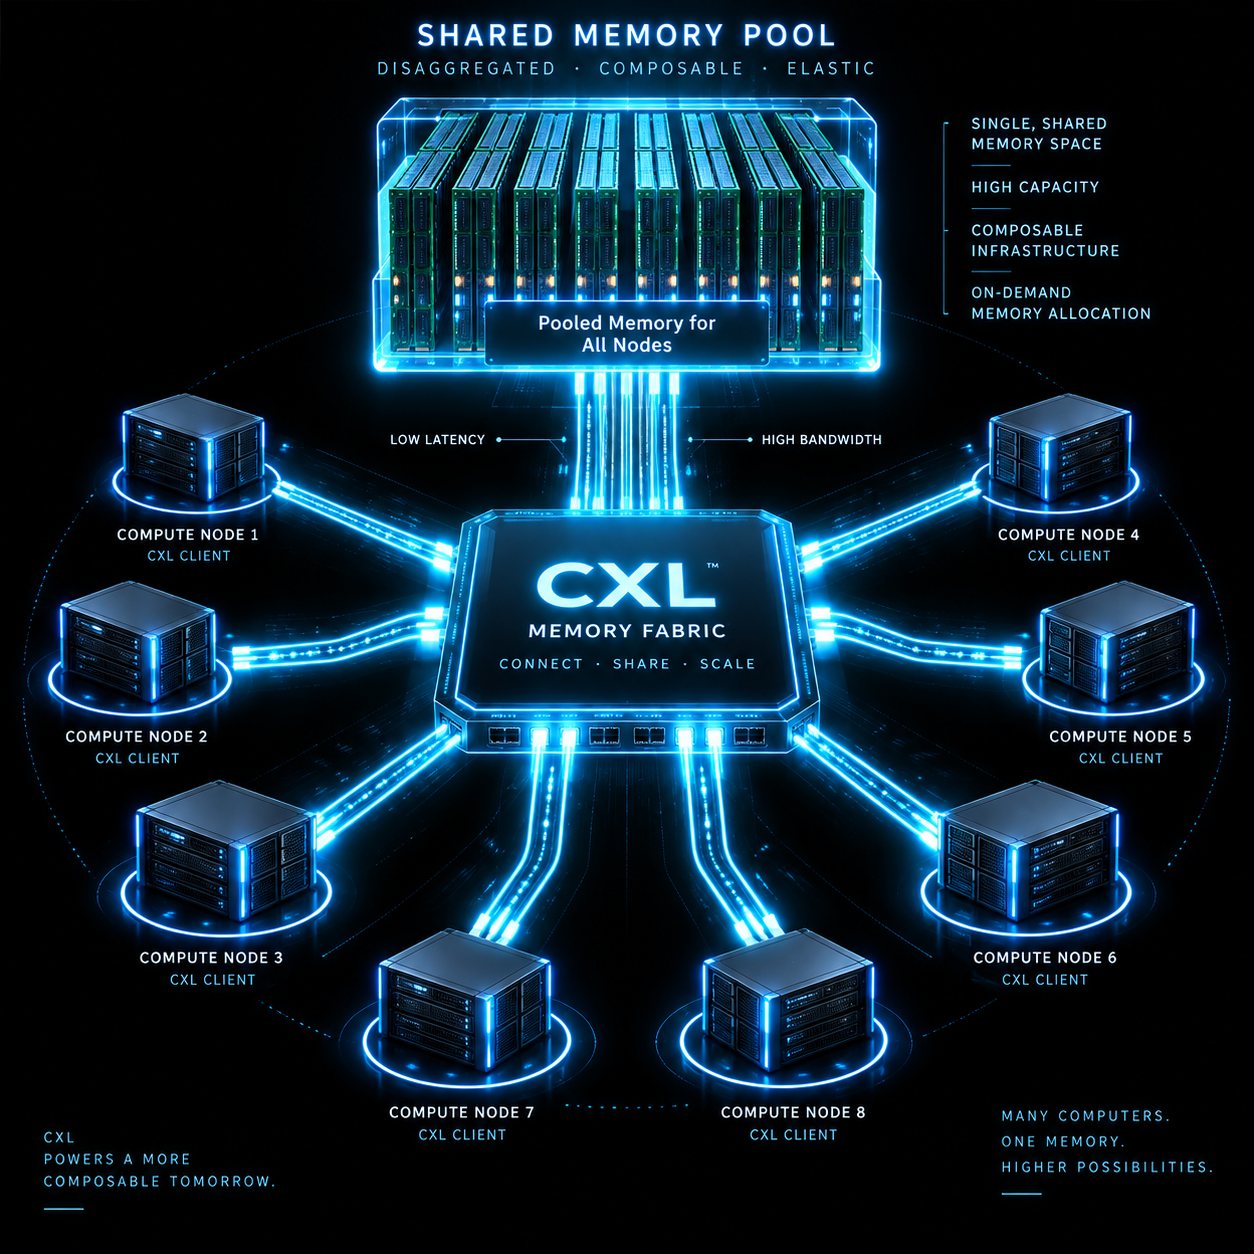
When inference is not needed, the card presents its memory as CXL memory on top of PCIe. The host maps it, and the capacity is not left idle.
Store the data, or push the compute
Use the card as storage for data: datasets, embeddings, KV caches. Or send the work to the data instead of moving the data to the work.
One design, two targets
The same card, the same LeoCore and the same LeoDISK memory interface serve both roles. No second product to buy.
02 / MANY CARDS, ONE MODEL
Large models,
many cards working together.
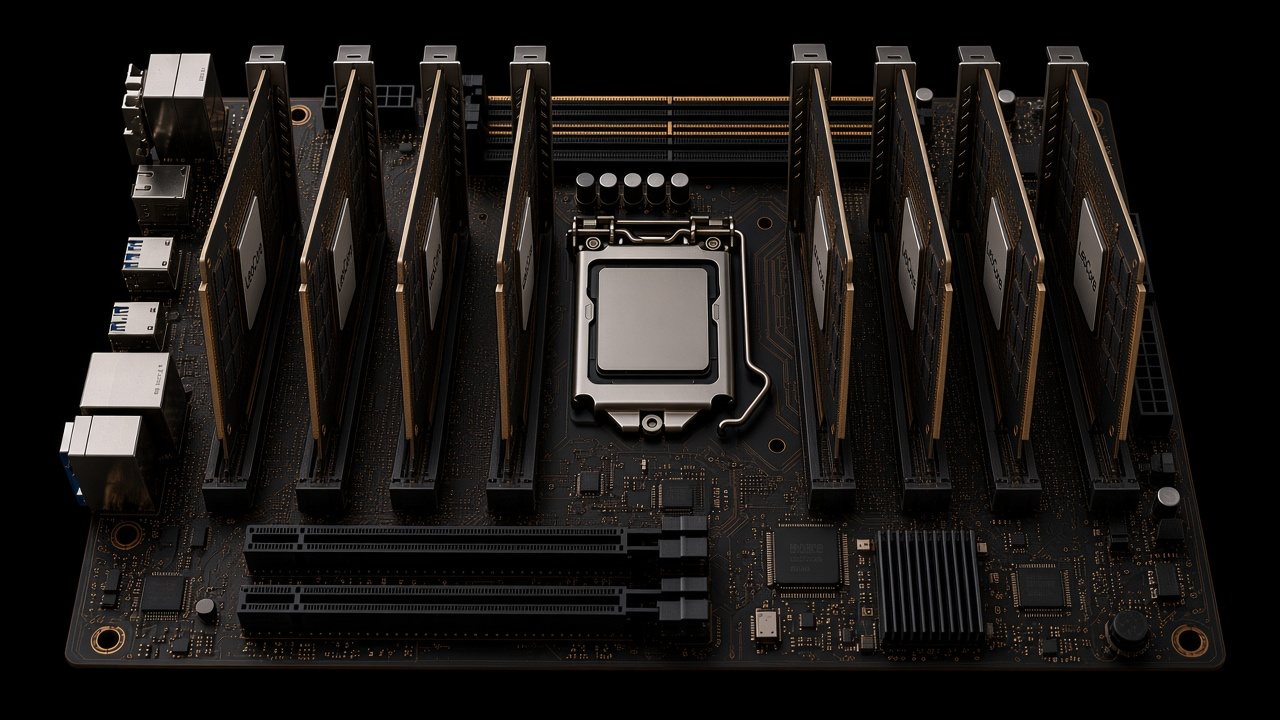
Fill a server with cards on both sides of the CPU and split a large model across them: tensor-parallel for a few users at low latency, or pipelined for many batch users. Only activations move between cards, so the links stay light.
03 / AT RACK SCALE
A rack of inference,
or a pool of memory.
Scale from one card to a server full of cards to a rack of servers. Run inference across all of them, or let the cards act as memory and turn the rack into a shared CXL memory pool for the compute nodes.